Perl udemy
Perl programming Udemy
Get DNS subroutine arguments
#!/usr/bin/perl
use strict;
use warnings;
use diagnostics;
use feature "say";

sub get_dns {

    (my $domain,my $rec_type) = @_;
    return my $data_dns = qx/dig +short $domain $rec_type/;
}
my $dns_values = &get_dns("vladmin-dev.top","A");

print("$dns_values\n");
Adding numbers with variable length parameter list
use strict;
use warnings;
use diagnostics;
use feature "say";

sub add_numbers
{
    my $sum = 0;
    foreach my $value (@_)
    {
        # print("$value, ");
        $sum += $value;

    }
    return $sum;
}

print(&add_numbers(1,2,3,4,5,100));
sed substitution in Perl
- global /g option
- Case insensitive -i option + -g option global substitution
Regular Expressions
#!/usr/bin/perl
use strict;
use warnings;

sub main {
    my $text = "The code for this device is GP5232.dda0ss2aas1s";
    if($text =~ /([A-Z]+\d{4}\.)/){
        print("The code is : $1\n");
    }else{
         print("Code not found!\n");
    }

    if($text =~ /\sis\s(.+?)(\.)/){
        print("The code is : $1$2\n");
    }else{
         print("Code not found!\n");
    }
    if($text =~ /\sis\s(\w\w\d{2,6}\.)/){
        print("The code is : $1\n");
    }else{
         print("Code not found!\n");
    }
}
main();
Working with files read/write operations
Check if file exists
#!/usr/bin/perl
use strict;
use warnings;
use feature "say";
use Term::ANSIColor qw(:constants);
say "Welcome to Perl";
$|=1; # Disable buffering
sub main {
    my $file  = 'robot2.png';
    my @files = ( 'image-download.pl', 'html-download.pl', 'test.pl','missing.txt' );
    foreach my $filename(@files){
        if(-f $filename){
        print("$filename\tFound!!!\n");
    }
     else{
        print("File not found\n");
     }
    }

    if ( -f $file ) {
        print("File Exists\n");
        my $command = qx/stat $file/;
        print("$command");
    }
    else {

        print( BOLD ITALIC RED, "$file\t", "$!\n", RESET );
    }
}
main();
writing text to file
#!/usr/bin/perl
use strict;
use warnings;

$|=1;

sub main {
    my $output = 'output-file.txt';
    open(OUTPUT,">",$output) or die("Cant Create $output\n");
    print(OUTPUT "Hello World");

    close(OUTPUT);


}
main();
reading from book text file
- Searching for eBook string from file printing only first 5 lines
- Using Dracula free ebook by Bram Stoker
#!/usr/bin/perl
use strict;
use warnings;
$|=1;

sub main {
    my $counter = 0;
    my $file = 'dracula.txt';
    open(my $fh,"<",$file) or die("Input file $file not found \n");
    while (my $line = <$fh>){
        # Check only first 5 lines of the book
        if($counter == 5){
            die("Enf of reading, Displayed lines $counter")
            # Print line if it contains word ebook
        }if($line =~ /ebook/){
            print("$line");
        }
        # Counter of the lines
        $counter +=1;
    }

   close($file);
}
main();
word replacing
#!/usr/bin/perl
use strict;
use warnings;
use Term::ANSIColor qw(:constants);
$|=1;
sub main {
    my $input_file = 'dracula.txt';
    open(INPUT,"<",$input_file) or die("Input input_file $input_file not found \n");
    my $output = 'output-file.txt';
    open(OUTPUT,">",$output) or die("Cant Create $output\n");

    while (my $line = <INPUT>){

     if($line =~ /(^dracula.+L)/i){
        #$line =~ s/Dracula/VAMPIER/gi; ## Substitution line
        print("$1\n");
        }

}
close(OUTPUT);
close(INPUT);
}
main();
csv file reading
- basic csv file reading
#!/usr/bin/perl
use strict;
use warnings;

$|=1;
sub main {
    my $input = "test.csv";
    unless(open(INPUT,$input))  {
        die "\nCan not Open $input\n";

    }
    <INPUT>; # cutting off he header
    while (my $line = <INPUT>){
        my @csv_values = split(',',$line);
        chomp(@csv_values);
       print("$csv_values[1]\n");

    }
    close(INPUT);
}
main();
- reference values in array and print them line by line
#!/usr/bin/perl
use strict;
use warnings;


sub main {
    my $input = 'test.csv';
    unless(open(INPUT,$input)){
        die("\nCan not open file $input\n")
    }
    <INPUT>; #Removing the csv headers
    my @lines;
    my $count = 0;
    while (my $line = <INPUT>){
        chomp($line);
       $lines[$count] = $line;
       $count++;
    }
    close(INPUT);
    foreach my $row(@lines){
        print("$row\n");
    }
}
main();
- instead count use push to add values to an array
referencing arrays
#!/usr/bin/perl
use strict;
use warnings;
use Data::Dumper;

# sub test {
#     my @animals = ('dog','cat','rabbit');
#     my @values;
#     my @fruits = ('apple','banana','orange');
#     push @values, \@animals;
#     push @values, \@fruits;
#     print Dumper("@values");


# }
# test();

$|=1;
sub main {
    my $input = "test.csv";
    unless(open(INPUT,$input))  {
        die "\nCan not Open $input\n";

    }
    <INPUT>; # cutting off he header
    my @lines = ();
    while (my $line = <INPUT>){
        chomp($line);
        my @csv_values = split(/\s*,\s*/,$line);

        push @lines,\@csv_values;
    #   my $new_string = join('|',@csv_values);
    #   chomp(@csv_values);


    }
    close(INPUT);
    print($lines[3][1] . "\n");
     foreach my $line (@lines){
    print Dumper( $line );
    }
}
main();
- de-referencing the array with ->
sub main {
    my @components = ('pc','laptop','mouse','keyboard');
    my $values_ref = \@components;
    print $values_ref->[1];
}
main();
- Skip blank lines in file
 $line =~ s/^\s*//; # replacing beginng of the line spaces
 $line =~ s/\s*$//;  #Cleaning space at the end
 $line =~ /\S+/ or next; # Skipping Blank Lines
web scraping regex
- Explanation:
<img\s+: Matches the <img tag followed by one or more whitespace characters (\s+).[^>]*: Matches any characters except > (ensuring it doesn't prematurely match the end of the tag).src="([^"]+)":- Matches the src=" part.
([^"]+): Captures everything inside the src attribute's quotes until it finds the next " (excluding the " itself).
#!/usr/bin/perl
use strict;
use warnings;
use LWP::Simple;

sub main {

    my $content = get("https://example.com");
    unless(defined($content)){
        die("Site Unereachable")
    }
#(^<img\s*src\=\"https*\:\/\/\w+\.\w+\/*+\/?>$)
    while ($content =~ m|(<img\s+[^>]*src="([^"]+)")|sig){
        print("$1\n");
    }

}
main();
- extract classes with regex
#!/usr/bin/perl
use strict;
use warnings;
use LWP::Simple;

sub main {

    my $content = get("https://example.com");
    unless(defined($content)){
        die("Site Unereachable")
    }
   my @classes = $content =~ m|class="([^"']*?)"|ig;
    if(@classes == 0){
        print("No Matches");
    }else{
        foreach my $class (@classes){
        print("$class\n");
        }
    }
}
main();
Getting data into database DBI module
#!/usr/bin/perl
use strict;
use warnings;
use Data::Dumper;
use Getopt::Std;
use XML::Simple;
use feature "say";
use DBI;

$| = 1;

=pod

    This is ACME XML parser version 1.0
    Use with care.

=cut

sub main {
    my %opts;

    # Get command line options
    getopts( 'd:r', \%opts );

    if ( !checkusage( \%opts ) ) {
        usage();
        exit();
    }

    my $input_dir = $opts{"d"};

    my @files = get_files($input_dir);

    my @data = process_files( \@files, $input_dir );

    add_to_database( \@data );

    # add_to_database();

    # print Dumper(@data);

}
### ADD band name to the database
sub add_to_database {
    my $data = shift;
    my $dbh  = DBI->connect("dbi:mysql:bands");

    # my $dbh_albums = DBI->connect("dbi:mysql:albums");
    unless ( defined($dbh) ) {
        die "Cannot connect to database.\n";
    }

    print "Connected to database \n";
    my $sth_bands  = $dbh->prepare('insert into bands (name) values (?)');
    my $sth_albums = $dbh->prepare(
        'insert into albums (name, position, band_id) values (?,?,?)');

    unless ($sth_bands) {
        die "Error preparing SQL Insert for Albums\n";
    }
    unless ($sth_albums) {
        die "Error preparing SQL insert for Albums\n";
    }

    # if ( $data eq "" ) {
    say "Deleting data from tables Bands and Albums";
    $dbh->do('delete from albums') or die "Cant Clean bands Table";
    $dbh->do('delete from bands')  or die "Cant Clean bands Table";

    # }
    # else {

    foreach my $data (@$data) {
        my $band_name  = $data->{"name"};
        my $albums = $data->{"albums"};
        print("Inserting $band_name into the database\n");

        unless ( $sth_bands->execute($band_name) ) {
            die "Error Executing SQL\n";
        }
        my $band_id = $sth_bands->{'mysql_insertid'};
        foreach my $album (@$albums){
        my $album_name = $album->{"name"};
        my $album_position = $album->{"position"};
        # print "$album_name,$album_position\n";

        unless($sth_albums->execute($album_name,$album_position,$band_id)){
            die "Unable to execute albums insert.\n"
        }

        }


    }

    # }

    $sth_bands->finish();
    $sth_albums->finish();
    $dbh->disconnect();
    print("Disconnected from database\n");
}

#Processing FIles folder
sub process_files {
    my ( $files, $input_dir ) = @_;

    my @data;

    foreach my $file (@$files) {
        push @data, process_file( $file, $input_dir );
    }

    return @data;
}

#Processing a single file
sub process_file {
    my ( $file, $input_dir ) = @_;

    print "Processing $file in $input_dir ... \n";

    my $filepath = "$input_dir/$file";

    open( INPUTFILE, $filepath ) or die "Unable to open $filepath\n";

    undef $/;

    my $content = <INPUTFILE>;

    close(INPUTFILE);

    my $parser = new XML::Simple;

    my $dom = $parser->XMLin( $content, ForceArray => 1 );

    my @output;

    foreach my $band ( @{ $dom->{"entry"} } ) {
        my $band_name = $band->{"band"}->[0];

        my $albums = $band->{"album"};

        my @albums;

        foreach my $album (@$albums) {
            my $album_name    = $album->{"name"}->[0];
            my $chartposition = $album->{"chartposition"}->[0];

            push @albums,
              {
                "name"     => $album_name,
                "position" => $chartposition,
              };
        }

        push @output,
          {
            "name"   => $band_name,
            "albums" => \@albums,
          };

    }    # foreach band

    return @output;
}

#Getting the list of files
sub get_files {
    my $input_dir = shift;

    unless ( opendir( INPUTDIR, $input_dir ) ) {
        die "\nUnable to open directory '$input_dir'\n";
    }

    my @files = readdir(INPUTDIR);

    closedir(INPUTDIR);

    @files = grep( /\.xml$/i, @files );

    return @files;
}

#Checking argument options
sub checkusage {
    my $opts = shift;

    my $r = $opts->{"r"};
    my $d = $opts->{"d"};

    # Image a is optional; don't really need to refer to it here at all.

    # r is optional
    # d is mandatory.

    unless ( defined($d) ) {
        return 0;
    }

    return 1;
}

sub usage {
    print <<USAGE;

usage: perl main.pl <options>
    -d <directory>  specify directory in which to find XML files.
    -r run the program; process the files

example usage:
    # Process files in currect directory.
    perl main.pl -d . -r

USAGE
}

main();
Grouping data with sql queries
-
Join Query
-
Regular query
-
Full Join query
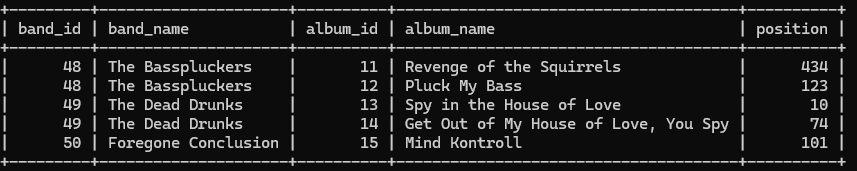
select b.id as band_id,b.name as band_name, a.id as album_id, a.name as album_name, a.position as position from bands b join albums a on a.band_id=b.id;
update array @INC to add new module folder within your code
- Example Speak.pm file
#!/usr/bin/perl
use lib ("/root/learn-perl5-by-doing/perl-packages");
use strict;
use warnings;
use Speak qw(test);

sub main {
    test();
}

main();
 my @module_list = ("/root/learn-perl5-by-doing/perl-packages","/root/learn-perl5-by-doing/perl-packages/test","/root/learn-perl5-by-doing/perl-packages/test2");

push @INC, @module_list;
- It can be either as an array @module_list or as a scalar pushing single value
- Example usage and output
#!/usr/bin/perl
use strict;
use warnings;


sub main {

    my @module_list = ("/root/learn-perl5-by-doing/perl-packages","/root/learn-perl5-by-doing/perl-packages/test","/root/learn-perl5-by-doing/perl-packages/test2");
    push @INC, @module_list;
    foreach my $module_dirs (@INC){
    print("$module_dirs\n");
    }
}
main();
### OUTPUT

[Running] /usr/bin/perl "/root/learn-perl5-by-doing/test.pl"
/etc/perl
/usr/local/lib/x86_64-linux-gnu/perl/5.38.2
/usr/local/share/perl/5.38.2
/usr/lib/x86_64-linux-gnu/perl5/5.38
/usr/share/perl5
/usr/lib/x86_64-linux-gnu/perl-base
/usr/lib/x86_64-linux-gnu/perl/5.38
/usr/share/perl/5.38
/usr/local/lib/site_perl
/root/learn-perl5-by-doing/perl-packages
/root/learn-perl5-by-doing/perl-packages/test
/root/learn-perl5-by-doing/perl-packages/test2